Practical Spectre-v2 Attacks in JIT Engines via Stale Branch Prediction Entries
We present Branch Target Reuse (BTR), a new Spectre-v2 attack targeting just-in-time (JIT) compilers. BTR affects the JIT engines found in web browsers, language runtimes, and the operating system kernel, across multiple CPU vendors. We analyzed the attack surface of Linux cBPF, Oracle GraalVM and SpiderMonkey (the JIT engine of the Firefox browser), and built two end-to-end exploits against the Linux kernel.
The key insight behind the attack is that, while modern CPUs restore architectural code coherence after self-modification, they do not necessarily invalidate stale indirect branch prediction entries (i.e., branch targets). In JIT engines, these stale targets can outlive the original code and later be reused when the code cache is repopulated, yielding a speculative execute-after-free primitive. This allows attackers to hijack speculative control flow to newly generated code at obsolete offsets, bypassing software hardening or reaching misaligned gadgets.
Figure 1 gives an overview of the attack.
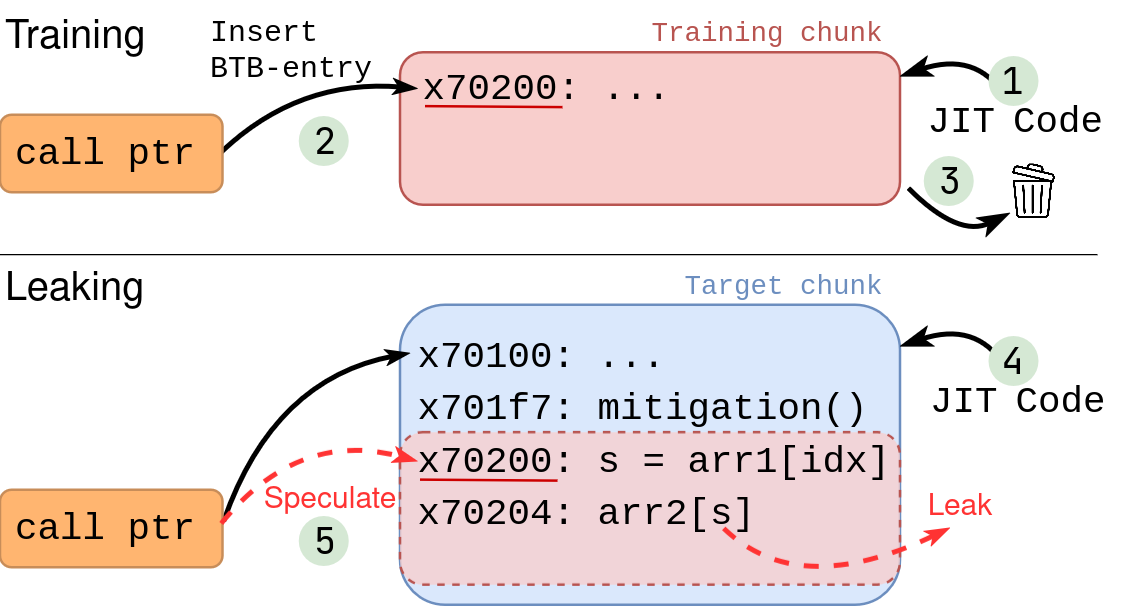 Figure 1: The attacker lures the JIT engine into allocating a new code section, the training chunk ①, and trains the indirect branch by jumping to it ②. Next, the attacker forces a deallocation of the training chunk ③ and an allocation of the target chunk that partially reuses the same address ④. When the attacker triggers the indirect branch again, the CPU uses the now-stale branch target buffer (BTB) entry and speculatively jumps to the old training-chunk entry point ⑤, resulting in control-flow hijacking and secret data disclosure.
End-to-end exploit on Linux cBPF
We built an end-to-end BTR exploit that leaks arbitrary memory on modern Intel CPUs, bypassing all enabled mitigations. Check out the demo below!
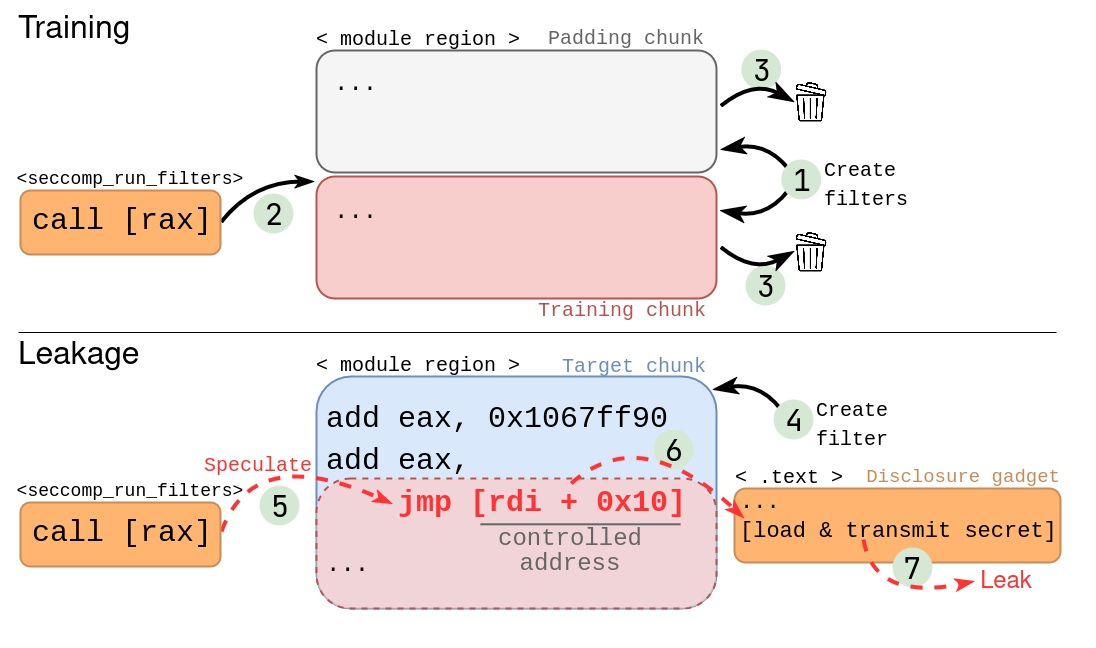
Figure 2: BTR exploit with Linux kernel cBPF.
Our exploit leaks 8 bytes per second. That may sound slow, but with careful pointer chasing we only need to leak a small amount of data to reach the secret. In the demo above, we leak the root password hash from the “su” process. We first run “su root”, which loads the root password hash into memory.
Once the attack is set up ([0:42]), we walk the Linux kernel task list. Since it is a linked list, we walk it backwards by leaking each “prev” pointer. For every task struct, we check whether the PID matches our victim. Once we find the correct task struct ([0:52]), we leak the “mm” struct and start walking the page tables. For every mapped page, we check whether it contains the root password hash. Once we find the correct page, we leak the hash! 😎
Bypassing cBPF constant-blinding
The Linux kernel can harden cBPF at runtime with the `bpf_jit_harden` option (see Linux documentation). When enabled, it applies constant blinding to immediate values to prevent direct JIT spraying. The option is off by default, but we took on the challenge of bypassing it anyway, and succeeded! We adapted an existing JIT-spraying technique that encodes instructions in jump offsets and applied it to cBPF for the first time. See the details below.
SpiderMonkey
SpiderMonkey is the JavaScript and WebAssembly engine of Firefox. Like every modern JS engine, it compiles hot code just-in-time for performance reasons, and that JIT engine is exactly what we attack. Because since site isolation is not fully deployed yet, other tabs can end up in that same address space, making their data a perfect target. This makes for a simple yet realistic threat model: a malicious web page controls the JavaScript running in the victim’s own browser, and turns BTR loose to leak the user’s sensitive data. We asked whether BTR is possible in SpiderMonkey, and the answer is very likely yes — it rests on three features of SpiderMonkey’s design.
Like every modern JavaScript engine, SpiderMonkey JIT-compiles hot code for performance and recycles unused code, so where emitted code lands is up to the engine’s allocator. That allocator shows a telling tendency: it hands newly reclaimed memory straight back out, because freeing a contiguous range rewinds the allocation cursor to the base of that range, making the just-freed blocks the first to be served again. Worse, this is only minimally randomized, in stark contrast to the hardening practices that deliberately randomize placement to frustrate memory-reuse attacks. From this tendency we built our first sub-primitive: reliable executable memory reuse across the JS/Wasm boundary.
If the allocator is accommodating, the Wasm compiler is positively generous. Instructions that push multi-byte constants, such as ‘f64.const’ and ‘v128.const’, compile into PC-relative loads whose constants sit in a literal pool embedded inside the executable code buffer. This hands us a convenient spray nozzle for writing arbitrary attacker-chosen bytes into executable memory, including valid, 4-byte-aligned instruction sequences even on fixed-width ISAs such as Arm64. And because SpiderMonkey rarely applies constant blinding, again for performance, the bar for constructing the target gadgets we want speculative execution to jump into drops sharply.
The last barrier is the victim indirect branch: every JS call that resists inline caching and inlining funnels into a single shared call stub, ‘IonGenericCallStub’, whose load-jump core has no Spectre-v2 hardening. A single static branch normally holds one BTB entry, but because prediction is history-based, varying the preceding branch history maps this same branch to many entries we control.
We chained these sub-primitives into a proof of concept (PoC). On Intel CPUs, BTB entries survive the full deallocation and reallocation cycle, for an estimated leakage rate on the order of tens of bytes per second. Turning this into an end-to-end browser exploit requires further work, such as lengthening the transient execution window and building a covert channel that tolerates the reduced timer precision.
GraalVM
GraalVM is Oracle’s multi-language runtime, which JIT-compiles the code it runs. It offers a sandbox for untrusted guest code, and in its strictest mode that sandbox is explicitly hardened against transient execution attacks: every memory access the guest makes is masked so that it cannot reach outside the sandbox arena. The threat model here is code that you deliberately run in that sandbox, think of a plugin or a user-supplied script.
That masking, however, only helps if you enter the code at the top. We used GraalPy, GraalVM’s Python implementation, to generate functions whose compiled form contains an array access preceded by such a mask, and with BTR we speculatively jump _past_ the mask, straight into the load (just like Figure 1). The access is now unbounded and happily reads outside the arena. We do not even need to forge the gadget ourselves; the compiler already emits a suitable one, and a small amount of dummy code is enough to steer the attacker-controlled values into the right registers.
Memory reuse, in turn, is almost free here. Unlike SpiderMonkey, GraalVM does not reserve and manage its own region for JIT code; it delegates each allocation directly to the kernel. The kernel, applying little randomization of its own, tends to return a freshly freed region on the next request, so releasing one compiled function and requesting another places the new code over the old one, precisely the overlap BTR needs. We do get stable address reuse this way, and the engine is clearly vulnerable on its own.
So far, however, the engine’s own compilation and GC activity wipes the BTB entries before we can use them; garbage collection, in particular, causes a lot of noise. We do not think this is fundamental though, better scheduling or smarter memory massaging may well close the gap.
Deployed mitigations
We disclosed our findings to affected hardware and software vendors, which acknowledged our findings. The hardware vendors stated that mitigating mechanisms (e.g., IBPB) already exist, and that BTR mitigations should be deployed in software. The Linux kernel developers and Oracle have deployed mitigations.
Linux kernel. The kernel developers upstreamed a new mitigation for x86 that issues an IBPB on all cores when a cBPF program reuses a previously executed cBPF/eBPF region, and discourages such reuse as an optimization. The mitigation applies whether or not IBT is enabled. Two CVEs were assigned:
- CVE-2026-64507 – x86/bugs: Enable IBPB flush on BPF JIT allocation
- CVE-2026-64508 – bpf: Support for hardening against JIT spraying
Oracle. GraalVM instead hinders region reuse by randomizing JIT code-cache locations.
Mozilla. Mozilla considered IBPB-based mitigations, but is currently prioritizing the completion and deployment of site isolation.
See also the announcement published by Intel.
More details: cBPF constant-blinding bypass
Following the jump-offset technique introduced by Maisuradze et al. (2016), we bypass cBPF constant blinding by encoding attacker-controlled bytes in the offset bytes of forward jumps instead of in immediates. The same byte sequence can be decoded as a valid chain of cBPF jumps in one alignment and as a “dispatch” gadget when execution re-enters two bytes later, yielding an end-to-end exploit against cBPF even with blinding enabled.
Since the maximum forward jump offset is 0x014fc5, we control only the lower two bytes of the offset, and the upper bytes remain zero. To stay in the misaligned execution stream, we carefully select instructions so that the next instruction consumes at least one of the remaining bytes.
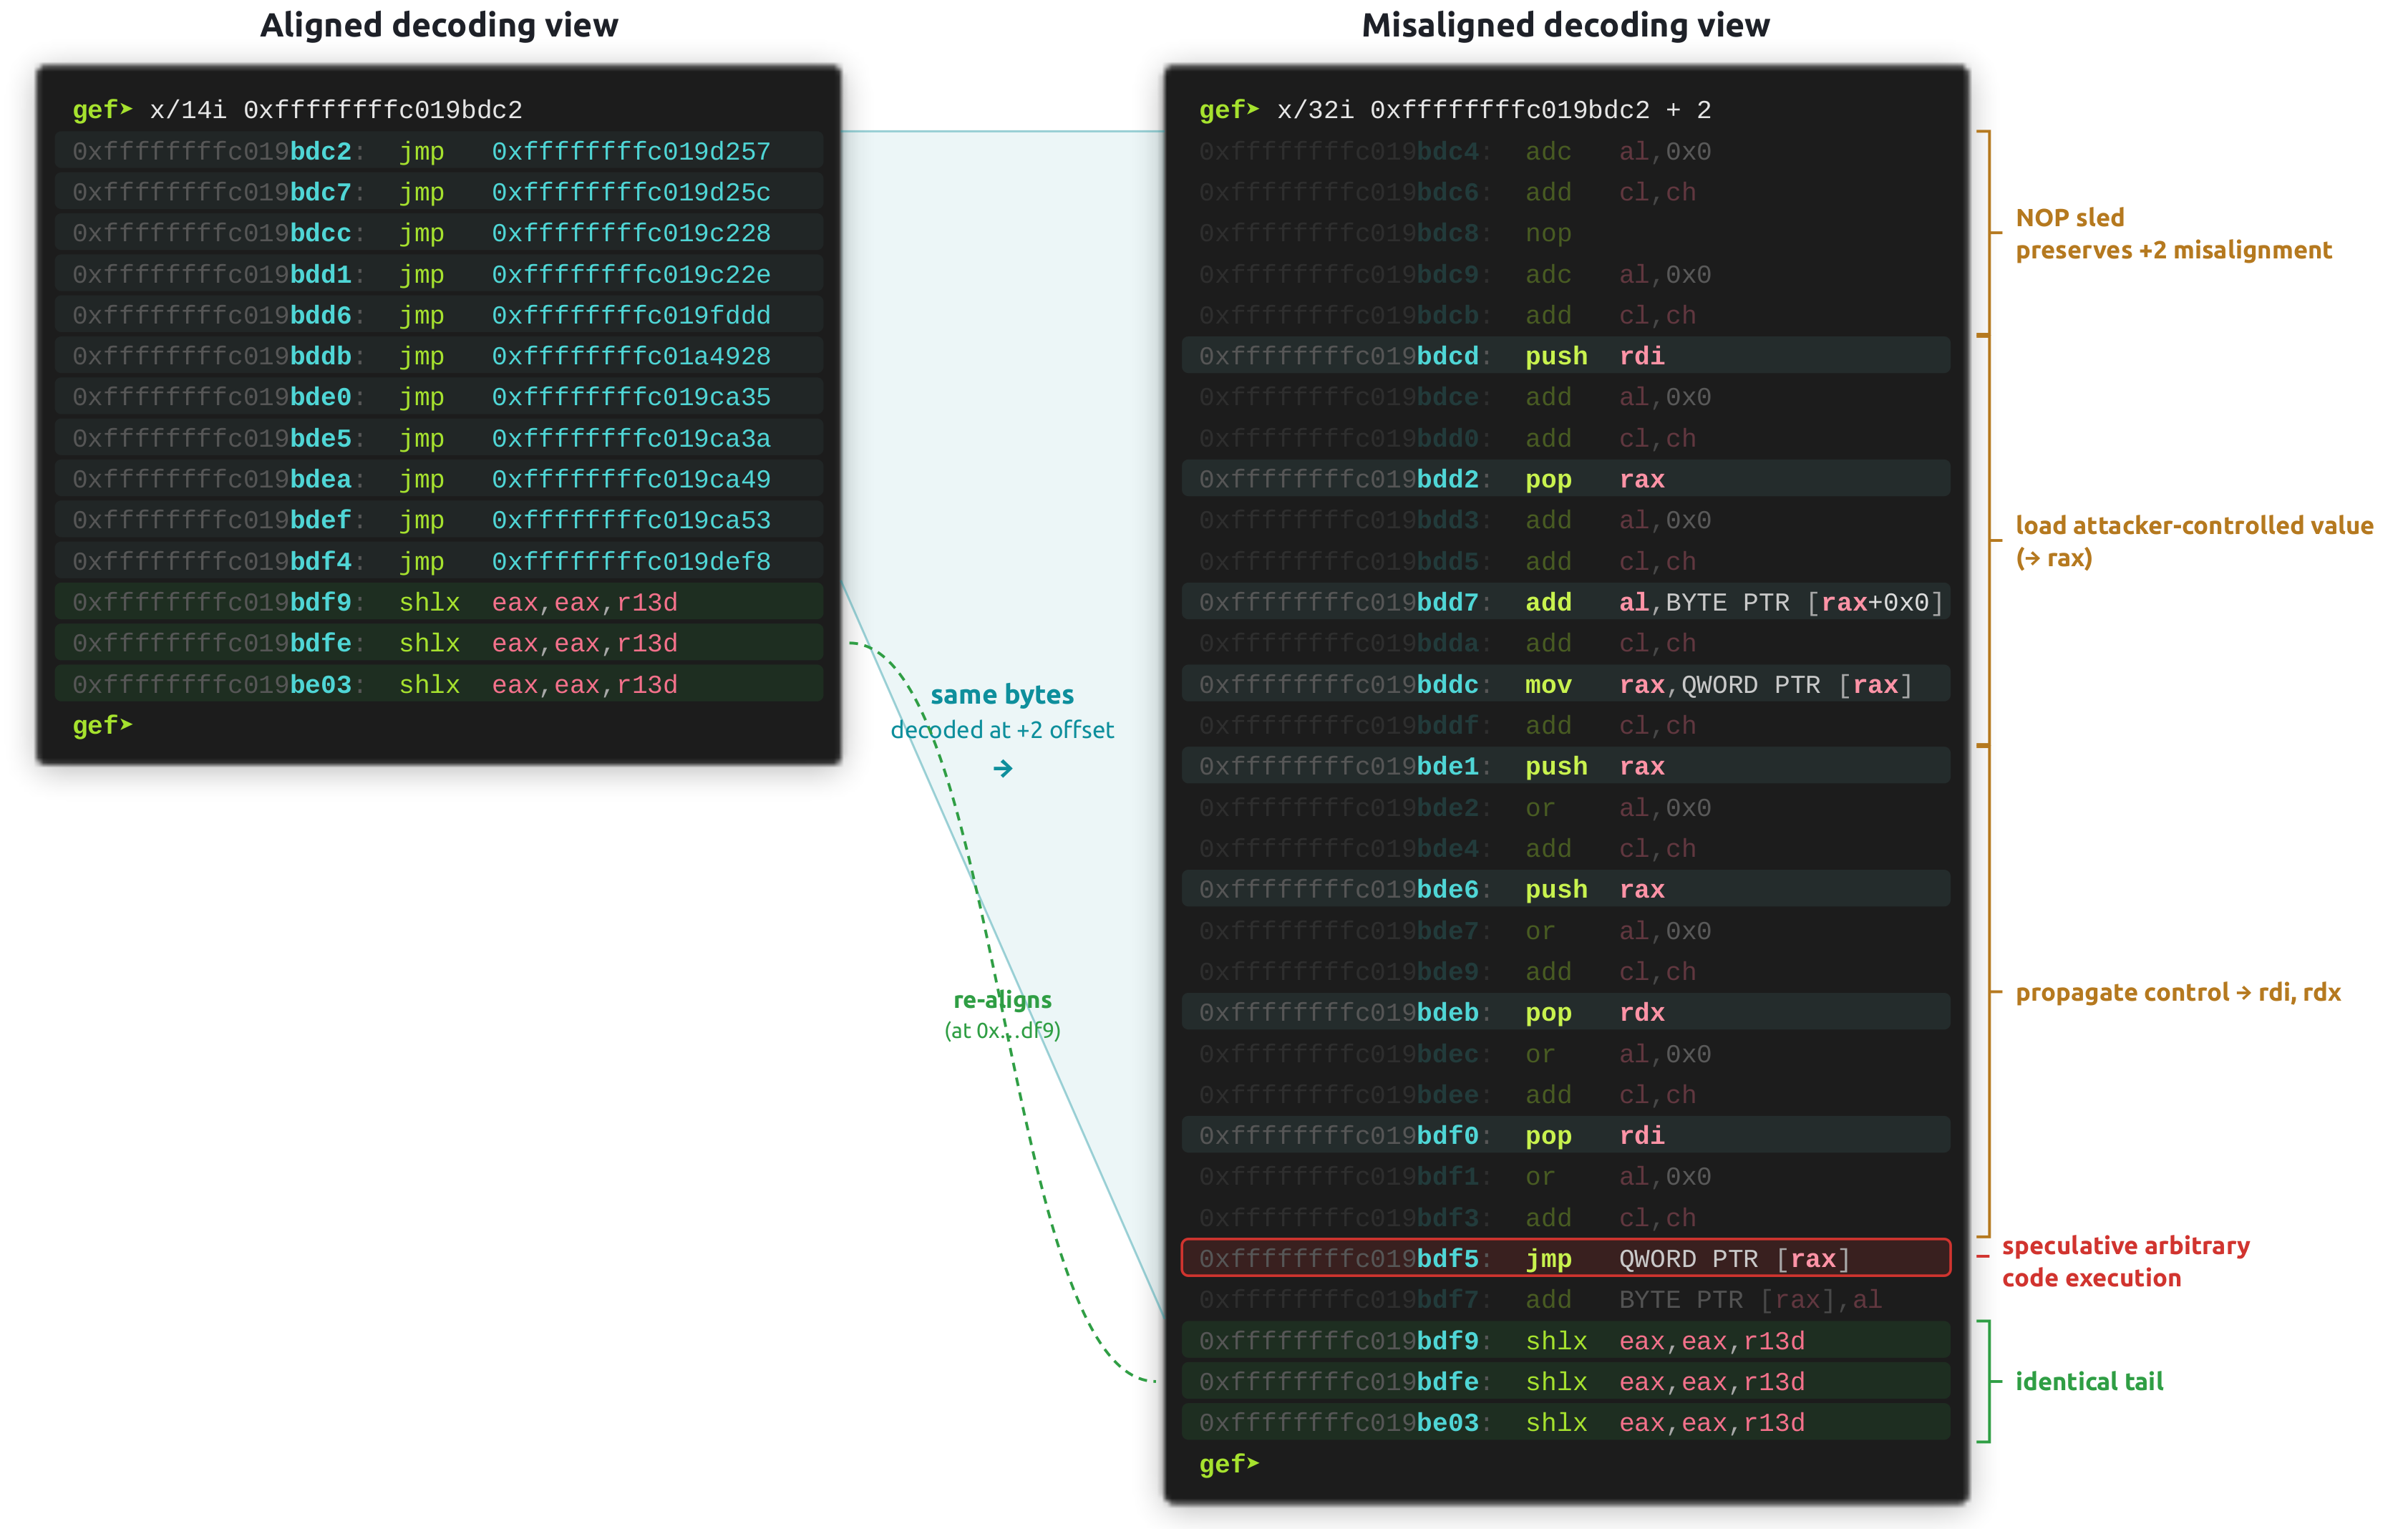
Figure 3: cBPF constant-blinding bypass via jump offsets. In the aligned view, the JIT emits a chain of valid forward jumps. In the misaligned view, the same bytes decode as a gadget that loads attacker-controlled data, propagates it to `rdi` and `rdx`, and then jumps to the disclosure gadget via an attacker-controlled indirect jump.
FAQ
Is my system affected?
Most likely. Indirect branch prediction is inherent to modern CPUs, and BTR exploits the desynchronization between the branch predictor and the actual state of the code. No current CPU has a mechanism to keep the two in sync, so until vendors add one, your CPU is vulnerable. We confirmed this behavior on every CPU we tested, covering Intel, AMD and Arm. Mitigation is left to software (see “Deployed mitigations”).
How do I protect my system?
Update your OS and software as soon as vendor patches are available. Both the Linux kernel and Oracle have released patches.
Does IBT/BTI protect me?
These mitigations raise the bar, but do not eliminate the risk. Indirect Branch Tracking (x86) and Branch Target Identification (Arm) require indirect branch targets to start with an `endbr64` or `BTI` instruction. On older Intel CPUs, one or more instructions can still execute speculatively before that check (Lion Cove is the first race-free Intel generation we found).
Even on race-free implementations, an attacker can inject bytes into JIT-compiled code that encode `endbr64` and reach them through misaligned execution, turning them into a valid landing pad. We were only able to do so with constant blinding disabled, which makes race-free IBT combined with constant blinding a much stronger defense. Exploitable gadgets may still exist on the speculative return path. See the paper for more details.
Wasn’t cBPF already disabled for unprivileged users?
Not quite. The more powerful eBPF JIT is restricted to privileged users, but the older classic BPF (cBPF) variant remains available to unprivileged programs. cBPF is intentionally tiny: it has only two 32-bit registers, supports only forward jumps, and forbids register dereferences. Those limits are exactly why it was historically considered safe enough for user-space filters, and why it is still widely used in Linux Socket Filtering (LSF), seccomp filters, and packet-filtering paths used by software such as Docker and Chrome, and in high-throughput network filtering.
More details
The “Branch Target Reuse” paper has been accepted for publication at the ACM Conference on Computer and Communications Security (CCS) 2026. The paper and code are linked below.